RAG(检索增强生成)终于正式出炉了。
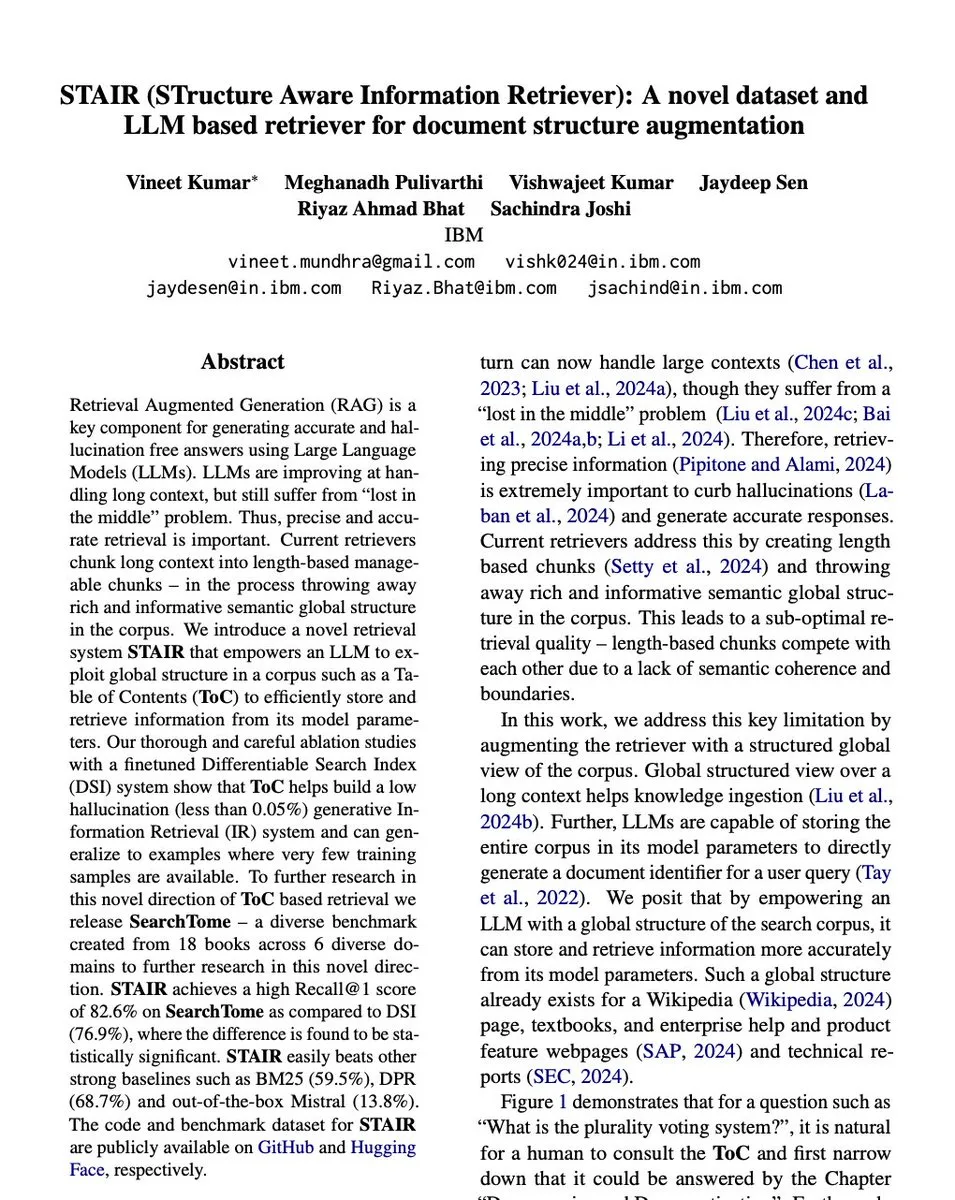
IBM构建了一款检索器,其 hallucination(幻觉)次数仅为细调RAG系统的65倍。
目前,每家公司都在使用检索增强生成(RAG)来阻止其AI产生幻觉。
这个想法是给AI一个私人的数据库,这样它就不会胡编乱造。
但有一个巨大的结构性缺陷。标准的RAG(Retrieval-Augmented Generation)系统盲目地根据向量相似性抓取文档,并强迫AI阅读它们。如果检索器拉取了无关的垃圾,AI不会停止。
它只是通过引用文献进行胡言乱语。
IBM刚刚发布了一篇彻底改变数学的文章。
他们构建了一个新的检索架构,比最先进的微调过的RAG系统低65倍。65x 是原型和生产级企业系统的区别。
他们系统主动过滤和验证从模型中检索的数据,而不是盲目地将上下文注入模型,希望一切顺利。它剔除了噪音,确保了绝对的精确性。
对企业来说,这便是圣杯。零幻觉意味着零责任。它意味着自主的智能体最终可以安全地处理敏感公司数据,而无需人类每一步的监控。
查看原文
原帖正文
RAG is officially cooked.IBM built a retriever that hallucinates 65x less than fine-tuned RAG systems.Right now, every company is using Retrieval-Augmented Generation (RAG) to stop their AI from hallucinating.The idea is to give the AI a private database to read so it doesn't make things up.But there is a massive structural flaw.Standard RAG blindly grabs documents based on vector similarity and forces the AI to read them. If the retriever pulls irrelevant garbage, the AI doesn't stop.It just hallucinates with citations.IBM just dropped a paper that changes the math entirely.They built a new retrieval architecture that hallucinates 65x less than state-of-the-art fine-tuned RAG systems.65x is the difference between a fun prototype and a production-grade enterprise system.Instead of blindly dumping context into the model and hoping for the best, their system actively filters and validates the retrieved data before the generation step even begins.It cuts out the noise. It forces absolute precision.For businesses, this is the holy grail.Zero hallucinations means zero liability. It means autonomous agents can finally be trusted with sensitive company data without a human babysitting every output.
引用自 X
原帖地址:https://x.com/i/status/2114979460495872355
原帖:
本站媒体副本
0 条评论
登录后可以参与讨论。
成员登录还没有评论。第一条认真回应会很重要。